Most B2B competitor analysis is a confident summary of the exact surfaces your competitor built to be summarized: the homepage, the G2 grid, the pricing page.
The real product, the real price and the real sales motion all live behind a gated call you will never get as yourself. So the average competitive deck is a faithful transcription of what a competitor wants you to believe, internally consistent and pointed in the wrong direction.
Mystery Demo is the one that gets past the storefront. We walk competitors’ funnels as a genuine buyer on a client’s behalf, sit the demos, get quoted the price, and hand back the recordings, transcripts, email threads and our analysis of everything the public page leaves out, on one Notion board.
From that seat, the same mistakes come up again and again, and they start with grading a rival off the one thing the rival controls most carefully.
You’re Analyzing the Storefront, Not the Store
Almost everyone grades the homepage, the review grid and the pricing page as if they were the product itself.
Those are the three surfaces a competitor shapes most carefully, and the easiest three to screenshot, so they become the analysis by default. A claim on a homepage sits at the bottom of any evidence scale: nobody showed it working, and the company that wrote it is the only source.
The feature a homepage leads with can be the one its own onboarding buries. The marketing site and the live demo are built by two different teams optimizing for two different things, and the order of emphasis flips between them often enough to matter.
Part of why teams stop at the surface is that almost nobody is responsible for going deeper. In many B2B SaaS companies competitive intelligence is a side-of-desk duty, so the work defaults to whatever surface is fastest to capture.
The Real Price Is Never on the Pricing Page
“We compared their pricing” is the most confident wrong sentence in competitive analysis.
The published tier and the number on a call can part ways quickly: a few “tell me about your team size” questions, an end-of-quarter nudge, and the figure the rep quotes is no longer the one on the site. At that point your spreadsheet is comparing the wrong column.
A pricing page is where the negotiation starts, not where it ends. The number that decides the deal arrives in the call and the follow-up after it, two places a published-tier spreadsheet never reaches.

That call is where Mystery Demo works. We build a buying scenario fitted to each competitor, book its demo through the normal front door, and sit every meeting until the number comes out, with the conditions attached: the metric it bills on, the minimum commitment, the term that earns the discount.
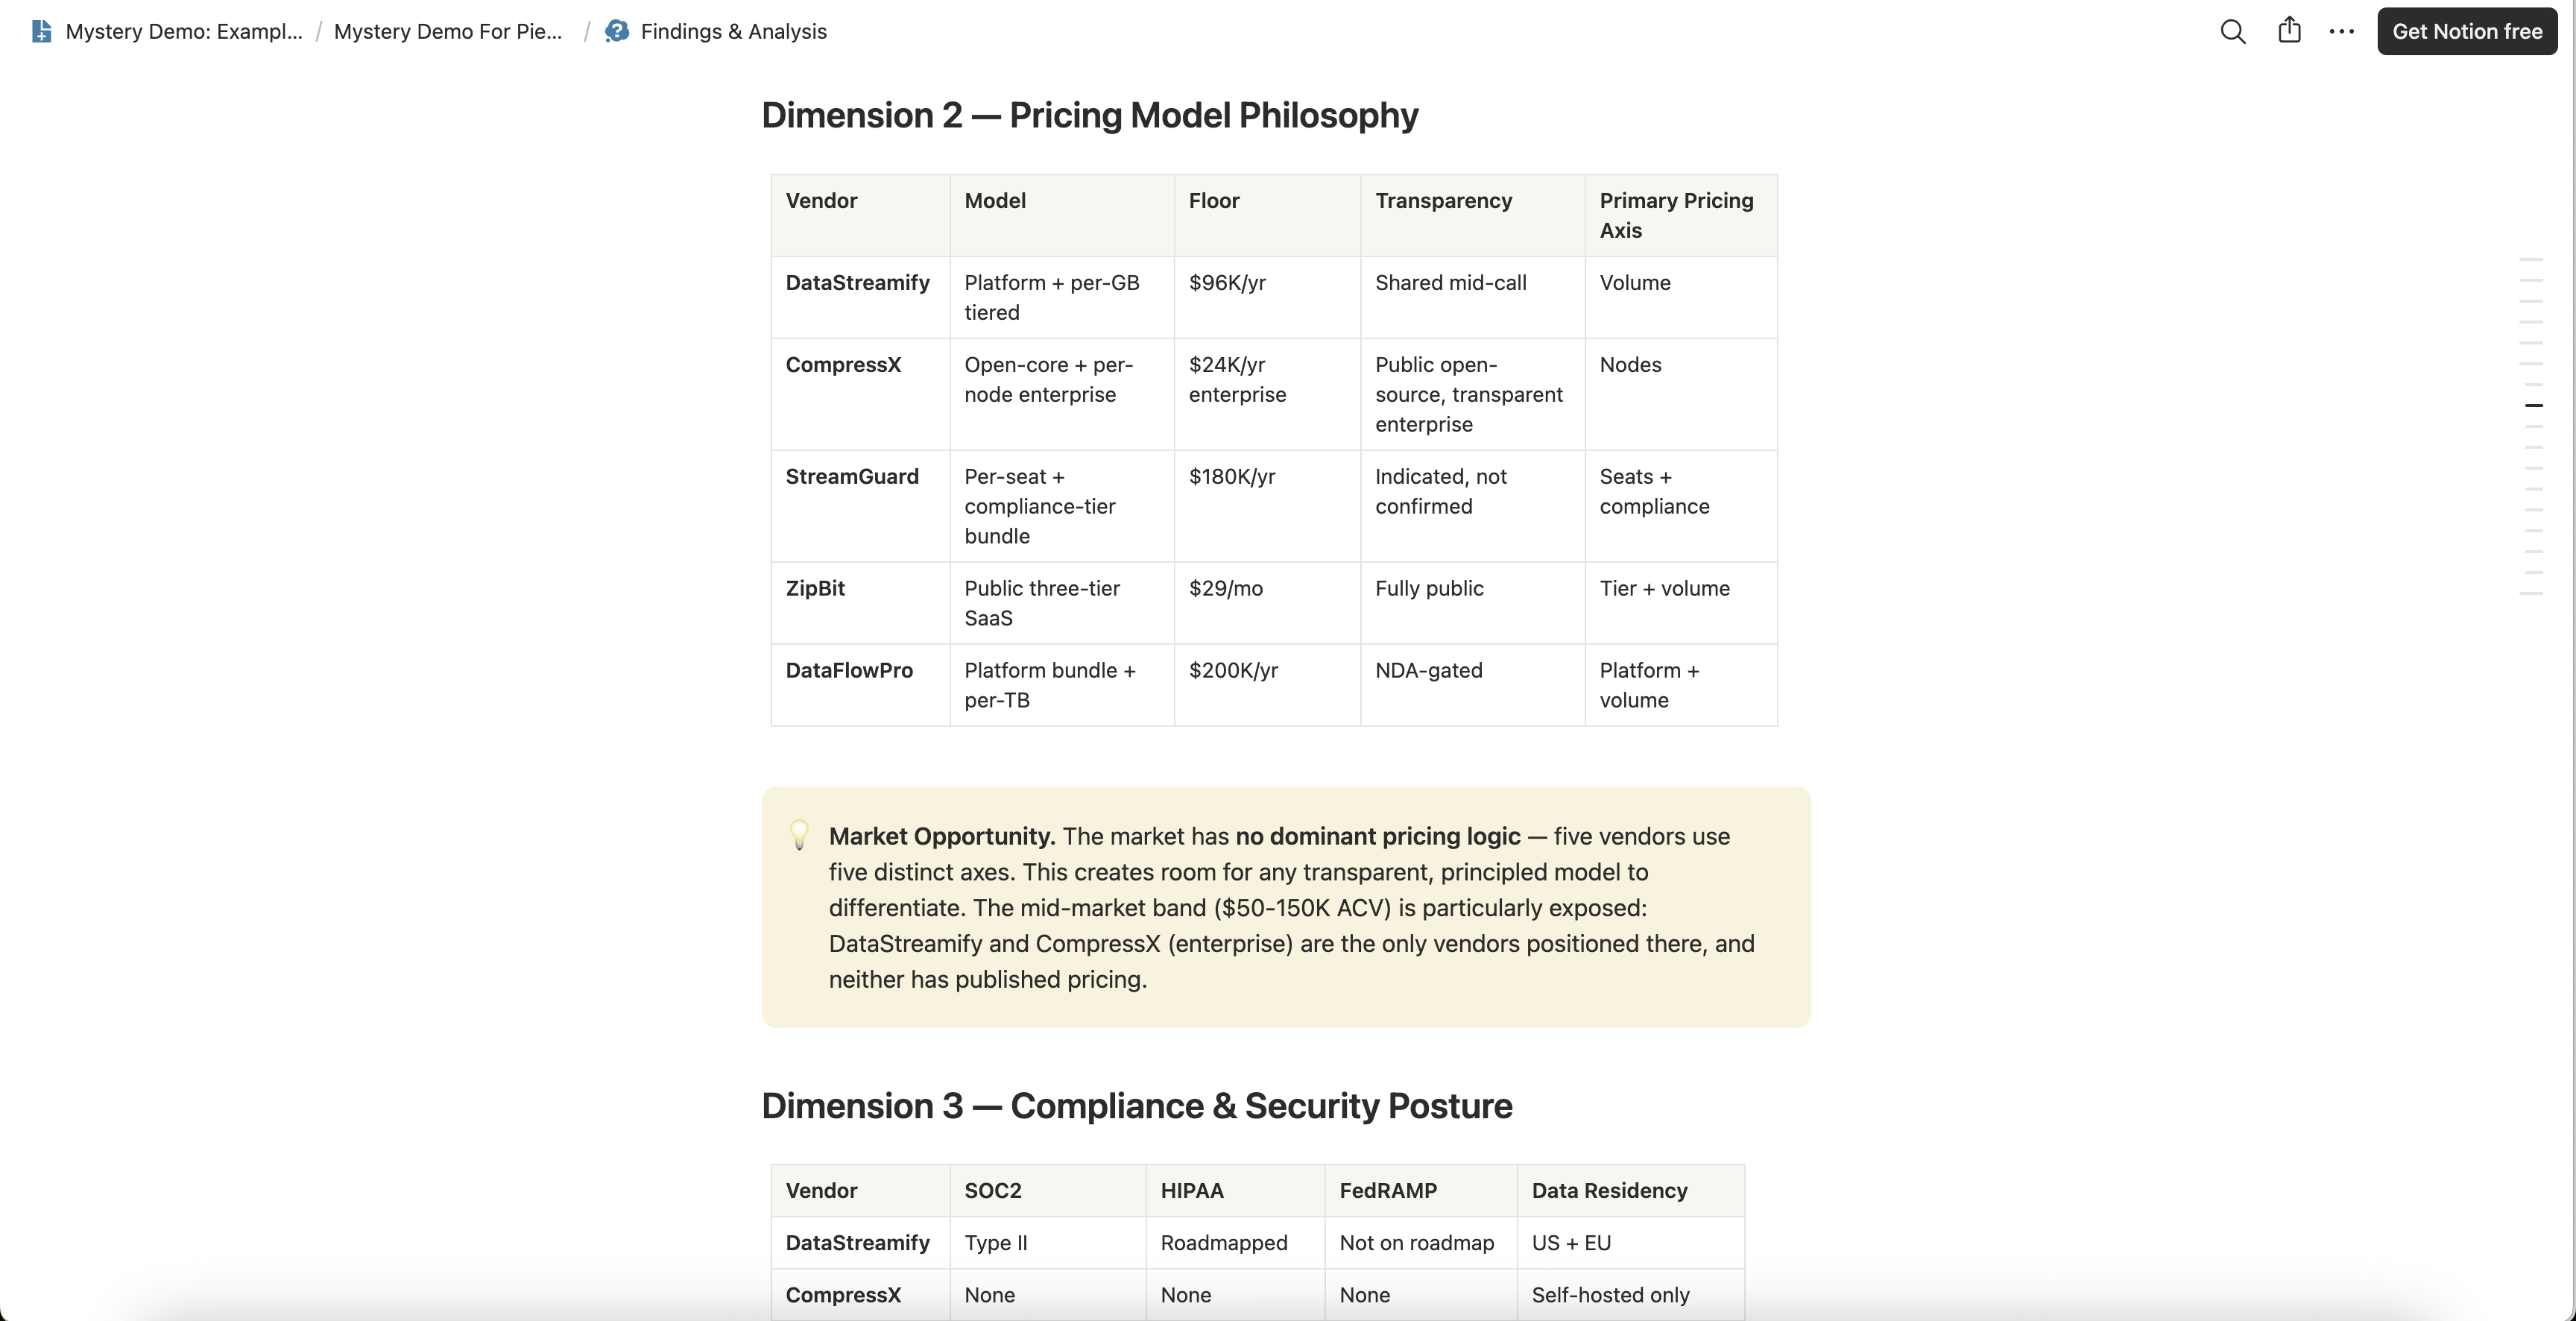
Below is the pricing page of Mystery Demo’s public example board, where every company is invented; a real project’s board is built from its own calls. Each competitor’s model, floor and transparency sit side by side, which is the comparison a published-tier spreadsheet cannot make.
Capturing that number is the job of a competitor pricing review, and it runs on a fixed fee: 499 euros per competitor, every meeting and the analysis included, five competitors at 2,495 and ten at 4,990. One competitor takes one to two weeks.
If your pricing sheet is still comparing published tiers, name the rival whose quote you most need on a short intro call. Mystery Demo will sit its demos and bring the number back with its conditions, recorded.
Your Battlecard Describes a Competitor That No Longer Exists
Even a perfect audit decays, because it is a photograph of a moving target.
The battlecard has a confident answer for a plan the competitor quietly retired last quarter, and it marks “not available” against a feature that shipped since. The card is not wrong on purpose. It is describing a company that has already shipped past it.
Battlecards go stale because the review cadence most teams can keep cannot outrun a competitor’s roadmap. Many teams update the card when someone loses a deal and asks, which means it is often stale before a rep ever opens it.
A card also inherits the source it was built from. One built from the website rebuts the website’s claims, while a card rebuilt from a recorded call answers what the rep says, in the rep’s own words. A recording ages too, but it carries its date, and running the same calls a year later shows exactly what moved.
Feature Parity Is the Wrong Scoreboard
The feature grid is comforting because it is checkable, and teams lean on it for exactly that reason. Feature parity is the most measurable thing in the room, which is roughly why it decides so few deals.
Deals often turn on the sales motion, not the checkbox count: a short paid pilot, a named onboarding human, a procurement process built to remove friction. None of that is captured by a feature comparison, and none of it shows up on the homepage.
By the time your rep is explaining a missing checkbox, the competitor may already have handed the buyer a cleaner pilot and a procurement path with fewer sharp edges. The parts worth stealing usually surface only after the public comparison has run out of things to say. On a call they are still promises, so treat each one as something to check:
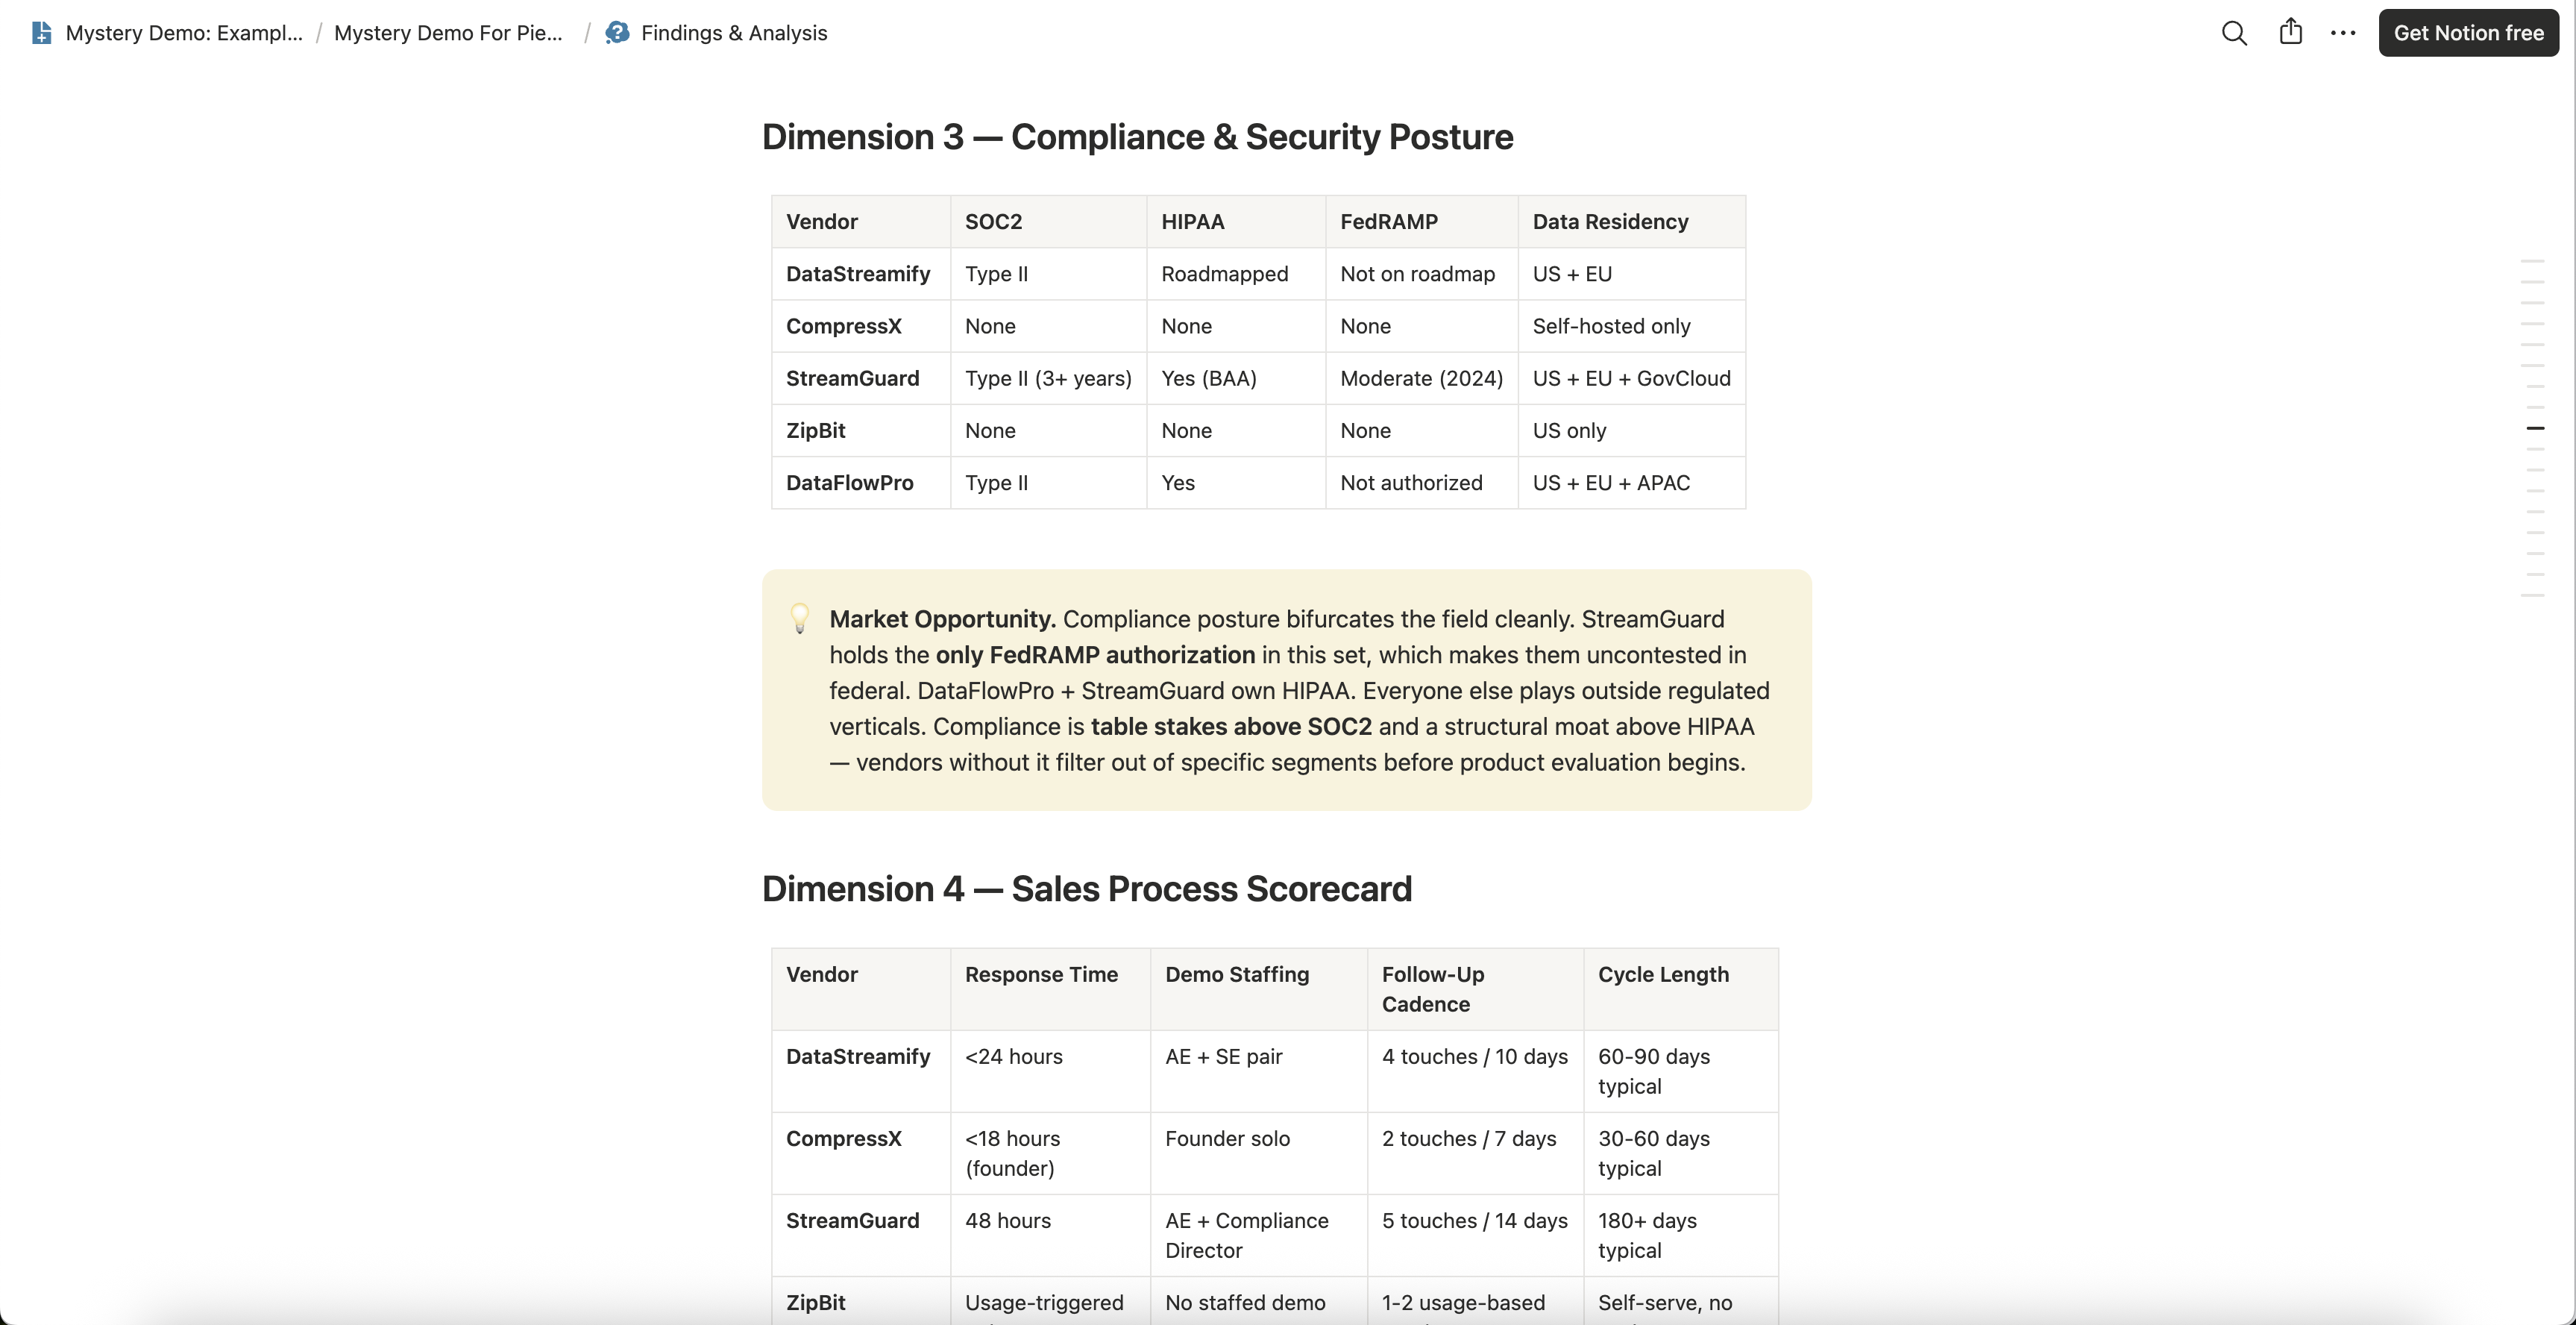
Some of that motion leaves a record a buyer can compare. The compliance page of the same invented board puts each competitor’s security posture in one table, the answers a buyer’s security team asks for before anyone signs. It cannot show how smooth a procurement will feel, but it shows which competitor had the answers ready.
Walking that motion end to end, the same way a buyer does, is most of what a competitor product comparison turns up.
Nobody Owns This, So It Decays by Default
When no title on the org chart says competitive intelligence, no one is officially on the hook when it slips. It is everyone’s job at planning time and no one’s job by week six, so it lands back on the public page, the one surface anyone can grab in five minutes.
Competitive research gets a budget at planning time and a folder that stops being opened a few weeks later. The one source of gated truth, walking the competitor’s funnel as a buyer, is the step teams skip, because it takes time, a credible buying scenario, and a willingness to sit through a rival’s pitch without flinching.
So they fall back on the record they do keep, and that record is unreliable. Closed-lost reasons get logged by the rep who just lost the deal, and across more than 100,000 B2B purchase decisions, Corporate Visions found sellers and buyers gave drastically different reasons for a loss 50 to 70% of the time.
If the reason on the card is that unreliable, the competitor named beside it is worth checking too, and that is how teams can end up building battlecards against the wrong competitor.
Put the five mistakes side by side and they share one flaw: each grades what is easy to reach, while the evidence that decides the deal sits somewhere else.
| The mistake | What it grades | Where the deciding evidence lives |
|---|---|---|
| Grading the storefront | The homepage, the review grid, the pricing page | The demo, where the rep shows what works today |
| Comparing published prices | The tier on the site | The quote on the call, with its conditions |
| Trusting an old battlecard | Last quarter’s website | What the rep says this quarter |
| Scoring feature parity | Checkboxes | The pilot, the onboarding contact, the procurement path |
| Reading CRM loss reasons | The losing rep’s guess | What a buyer hears from the rival who wins |
A Mystery Demo project starts the other way round. The team’s question is agreed at kickoff, and every competitor in the set is asked about it.
You can keep grading competitors off the surfaces they built to be graded on, or you can find out what they do once the call gets real.
Pick the three names your team keeps losing to, and the one claim about them nobody can check from the outside. Bring both to an intro call, and Mystery Demo will take the calls, then hand back the quote, the demo and the follow-up terms your spreadsheet has been guessing at.